Flat AST
The core idea of flattening AST can be found in Flattening ASTs.
The AST still describes a tree, but its nodes live in indexed tables instead of separately allocated objects. Child edges use NodeId values rather than pointers or Box<T>, and an Ast context owns the storage and provides access to it.
- Pros: Fewer per-node allocations and better memory locality, with compact handles that remain stable as storage grows.
- Cons: Field access requires the AST context, and handles must be used with the context that created them.
Detailed Design
There are two parts to the design: untyped storage shared by all node kinds, and typed handles that identify nodes in that storage.
Universal AST
This part of the design is inspired by the Zig compiler and its parser design.
Ast borrows the source text and an arena allocator. Besides node and field storage, it keeps the root, source metadata, attached comments, and strings. The main storage fields are:
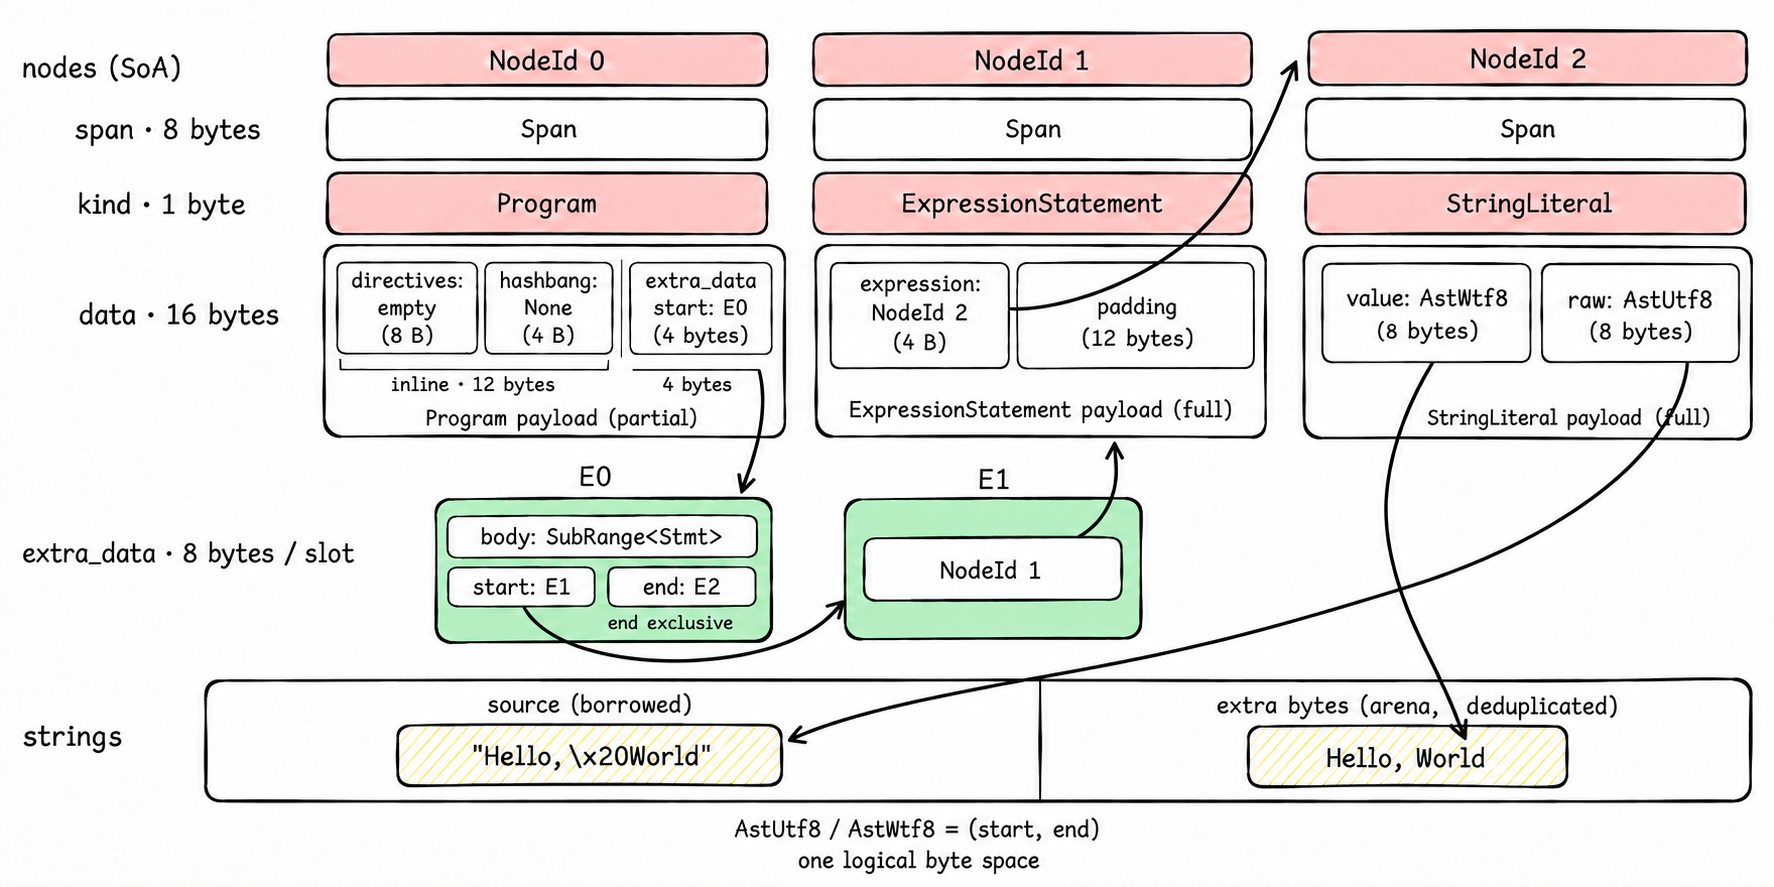
The node table uses a structure-of-arrays layout: spans, kinds, and payloads are stored in separate arena-backed columns, all indexed by the same NodeId. There is no stored AstNode record; AstNode is the trait implemented by typed handles.
Different node kinds have different fields. ast_tools computes a fixed layout for each kind, and generates a NodePayload union containing the corresponding typed payload structs. Fields are placed in the payload when possible:
- Full layout: All fields fit in the 16-byte payload; no extra field slots are needed.
- Partial layout: Selected fields occupy the first 12 bytes, and the last 4 bytes hold an
ExtraDataIdpointing to the remaining fields. Smaller fields are preferred to keep more fields inline.
For example, Program stores directives and hashbang inline, while body occupies one extra-data slot:
ExtraData is an 8-byte, type-erased slot. The AST schema supplies the field type and its encoding; no per-slot runtime discriminant is needed.
- Node handles are encoded as
NodeIdvalues. - Supported scalar fields are encoded as compact words.
AstUtf8,AstWtf8, andSubRange<T>store twou32offsets in one slot.- Optional handles and strings use reserved representations for
None, such asu32::MAXfor an optional node ID.
Typed AST
The typed handle representation is inspired by rowan. AST declarations describe the logical fields, while #[ast] turns each declaration into a copyable wrapper around a 4-byte NodeId:
AST enum declarations such as Expr and Stmt also become NodeId wrappers. Their concrete kind is read from the node table, so the handle does not carry a separate enum discriminant.
Handles do not encode ownership or an AST lifetime. They must refer to a valid node of the expected kind in the same context; unchecked construction or changing a node's kind must preserve that invariant.
Ast Tool
ast_tools reads the typed AST declarations and builds a shared schema of node kinds, fields, and enum variants. It computes each node's inline and extra-data layout, then generates the corresponding payload and storage code.
Inline fields access the concrete payload directly; spilled fields use extra_data_start plus a generated slot offset. Physical field order can differ from declaration order.